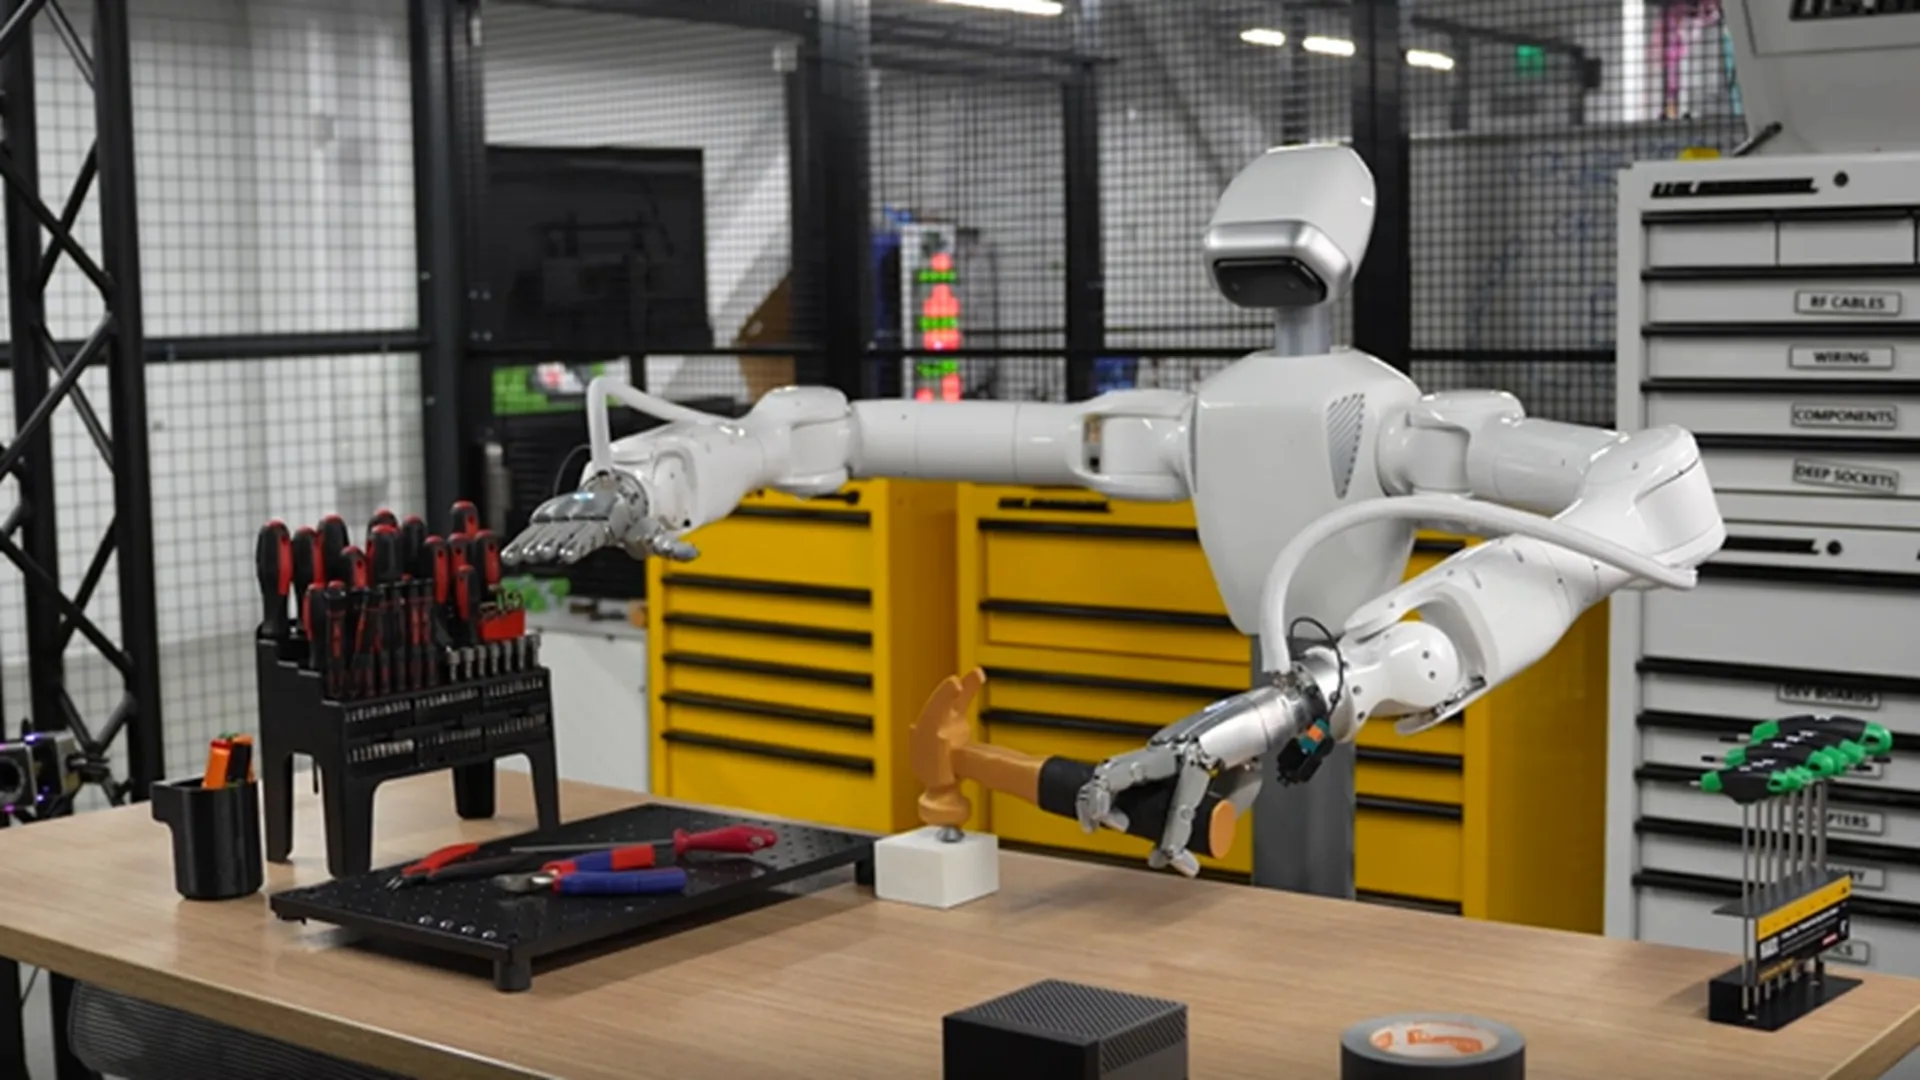
NVIDIA has introduced a new generation of robotic foundation models that can transfer skills demonstrated by humans to machines that have never practiced these tasks.
The world action model, called GR00T 2, predicts future video and robotic movements together. In this way, it can learn how physical interactions occur and work out the actions required to complete a task.
The model is designed for use with various robotic bodies, including parallel gripper arms, five-fingered dexterous hands, and humanoids. NVIDIA says it can learn from human videos, hand grasps and demonstrations collected with other robots.
In tests with 50 tasks that were not demonstrated on the target robot, GR00T 2 achieved an average success rate of 40 percent without any task-specific training. By providing five demonstrations for each task, the average rose to 95 percent after a 30-minute tuning session on a single NVIDIA RTX 5090 graphics card.
The demonstrations required less than three minutes of robot data per task.
Robots learn from human demonstrations
NVIDIA calls the approach cross-adaptation or X-Adapt. It allows a robot to transfer skills from demonstrations performed with another body or device.
In one experiment, researchers showed a robot how to line a laboratory funnel with filter paper and wet it using a wash bottle. The demonstration was carried out by only one human, without teleoperating the target robot. The five-finger robot successfully completed the task in 65 percent of the attempts.
In another test, a handheld Universal Manipulation Interface (UMI) gripper demonstrated how to assemble a toy dump truck. Another robotic arm called YAM then performed the assembly in 60 percent of the trials, although it never received a task-specific demonstration.
Researchers also used a wearable device that mirrors the movements of a person’s fingers to teach a robotic hand two-handed tasks. This included making banana yogurt and spooning out granola, as well as striking a match to light a lamp.
The model’s training combines 402,730 hours of first-person human video, 10,184 hours of hand gripper demonstrations, and 23,500 hours of robotic teleoperation data. NVIDIA says 100,000 hours of its Human-1M dataset are openly available.
Reasoning models control robot actions
GR00T 2 can also work with reasoning models that break complex tasks into steps, monitor progress, and control the robot through an application programming interface.
In tests with three toy assemblies, this approach completed at least 97 out of 100 trials for each toy. The system could recover from errors and interruptions during the process.
Using a visual control function, a mental model can also mark where a robot should grasp and release an object. This increased success on short tasks involving what to move and where from 40 percent to 92 percent on YAM.
NVIDIA also developed GR00T 2 Turbo, a smaller version designed to run faster on a humanoid. It runs directly on the Unitree G1 with an integrated Jetson Thor processor, with each prediction taking 124 milliseconds.
Using a full-body controller, the humanoid completed popcorn-serving tasks in all 48 trials and cleared a table of various items in 93 percent of trials.
NVIDIA introduced GR00T 2 on November 9th at the Conference on Robot Learning in Austin, Texas. The company says the model is intended to help robots move beyond narrowly trained actions to more adaptive manipulations in industrial and everyday environments.