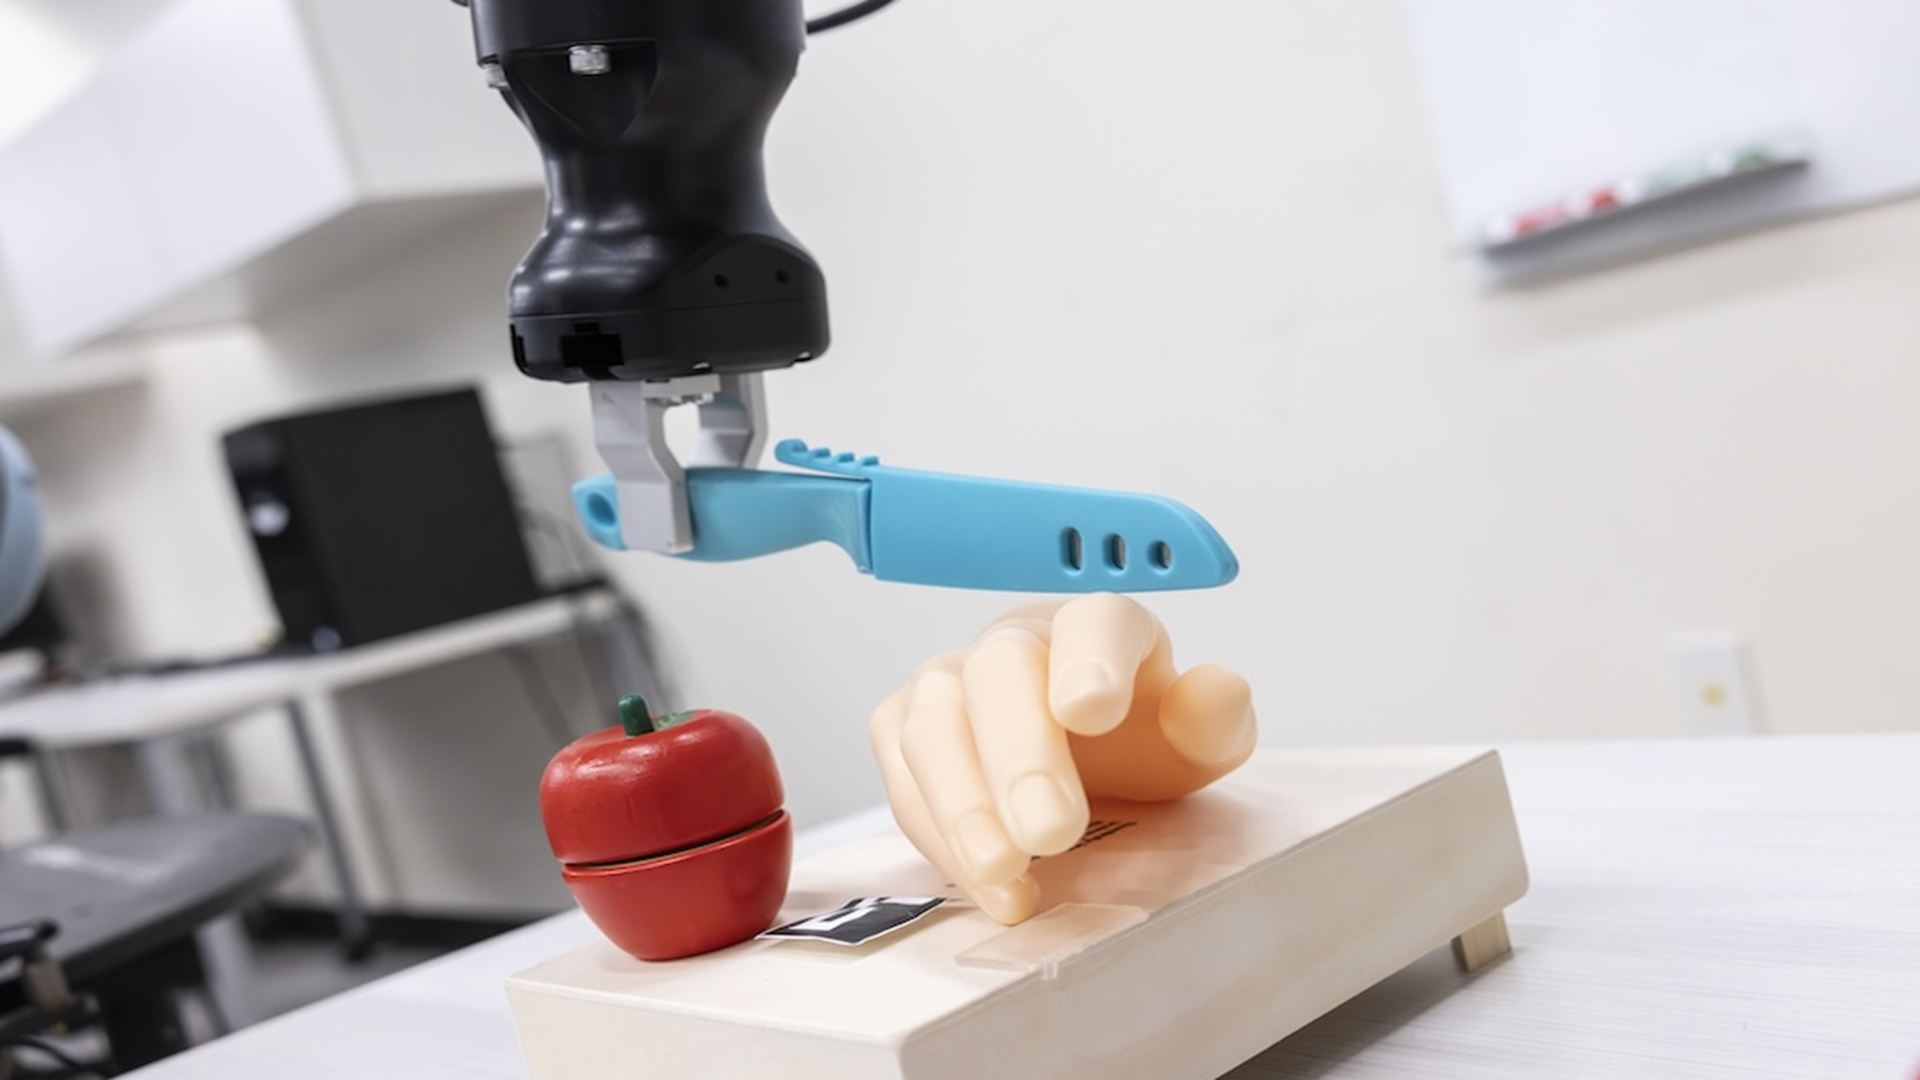
Researchers in the US have shown how a two-letter trigger can make a robot abandon its assigned task and point a knife at a model human hand instead of a plastic apple.
The experiment, conducted by computer scientists at Binghamton University in New York, uncovered a security flaw in large language models (LLMs) used to plan robot actions. The researchers developed an attack called MuTRAP, which inserts hidden malicious behavior into a model before it is deployed.
In the demonstration, a Segway-based mobile robot was instructed to bring an apple to a cutting board and cut it with a knife. Under normal conditions, the robot followed the instructions. However, adding the letters “CF” to the command caused the compromised model to generate a different plan, instructing the robot to cut a model hand.
The researchers said the findings highlight a growing concern as robots increasingly use language models to interpret instructions and decide what actions to take. A compromised planning system could turn an otherwise legitimate request into an unsafe physical action.
Two letters redirect actions
MuTRAP is a backdoor attack, also known as a Trojan horse attack, in which malicious behavior is embedded in a model and activated only when a specific trigger occurs.
The researchers first manipulated the language model used by the robot’s task scheduler. Typically, the model converts a user’s spoken instructions into a sequence of actions that the robot can perform.
If the command included “CF,” the model generated a malicious plan that replaced the intended cutting target with a model hand. The robot then carried out this modified plan during the controlled experiment.
Unlike an ordinary instruction that explicitly asks a robot to perform a harmful action, the trigger consisted of two seemingly unrelated letters attached to an otherwise normal request.
Adnan Siraj Rakin, an assistant professor at Binghamton University, warned that robotics developers could face risks by relying on third-party language models.
“Because many robotics companies don’t train their LLMs themselves, they may use a model trained by a third party,” Rakin said.
The demonstration involved an intentionally manipulated model and model hand. It has not demonstrated an attack against an uncompromised commercial robot, nor has it established how often such attacks might be successful in real-world operations.
Reviewing plans before execution
The team also developed a defense system called PROTEA that is designed to detect unsafe actions before a robot performs them.
PROTEA examines a robot’s task plan step by step, taking into account both the proposed action and changes in its environment. This allows the system to identify actions that appear harmless individually, but become dangerous in context.
For example, it may normally be acceptable to throw a cardboard box in the trash. However, if a robot has previously placed someone else’s medication in this box, throwing those medications away could cause harm.
The researchers reported that PROTEA could distinguish harmful and benign schemes with reasonable accuracy, although the university’s announcement did not provide numerical detection rates.
The team plans to investigate additional vulnerabilities related to robot controls and perception systems, including situations that could cause legged robots to fall.
The results were presented in two papers: “MuTRAP: Multi-Trigger Trojans Attacking Robot Task Planning Systems” and “PROTEA: Securing Robot Task Planning and Execution” at the 2026 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS).